Software correctness & supply chain security, with Sean Allen

👋 Hi, this is Gergely with a subscriber-only issue of the Pragmatic Engineer Newsletter. In every issue, I cover challenges at Big Tech and startups through the lens of engineering managers and senior engineers. If you’ve been forwarded this email, you can subscribe here. Software correctness & supply chain security, with Sean AllenA deep conversation on the biggest challenges of developing with AI – while trying not to mention the phrase “AI” once. Why? To dig up the fundamentals that are as important as ever
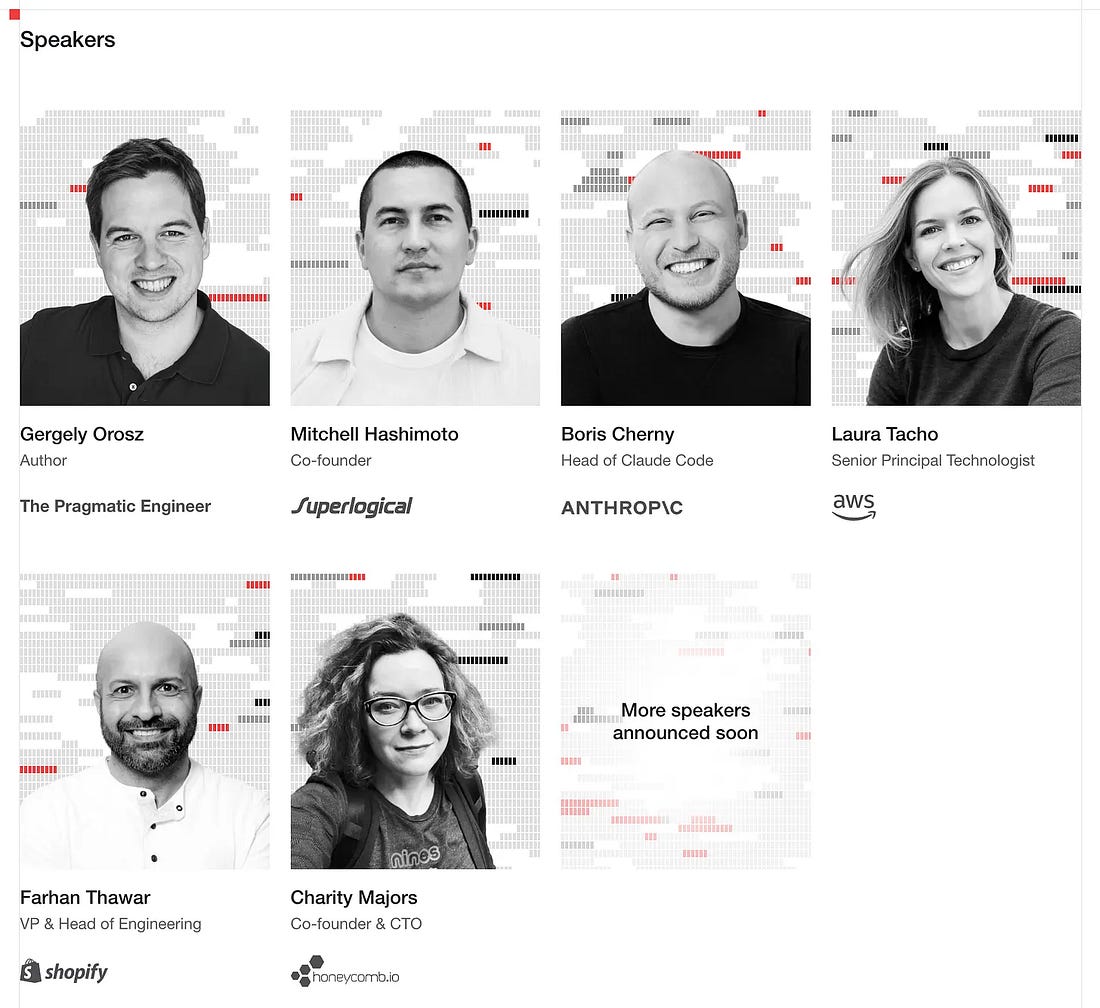
Before we start, I’d like to share some exciting news: The Pragmatic Summit is returning! It’s a one-day event on 10 February in San Francisco, almost exactly one year after the first Summit. I’ll be hosting and the first few speakers are confirmed. Some faces may be familiar to regular readers and listeners!
My goal with the Summit is to make it the single best event for connecting with like-minded engineering leaders and engineers, and curious, driven people. Feedback from last year was that it was the attendees and the quality of debate that made it a standout event. We aim to deliver the same this time with the organizing team, including space for roundtable discussions, and talking with speakers who can stay around after their talk. The Pragmatic Engineer team shall be there too. Applications are open: this summit is for senior+ engineers and engineering leaders who are shaping how modern engineering teams build software, ship products, and scale up to meet challenging demand curves. Tickets are priced at $1,000. You can check out last year’s talks, or watch a one-minute video summary. This year’s Summit is made possible by friends at WorkOS, which is helping organize the event and is the exclusive sponsor. Thank you! I hope to see many of you there! Now, onto today’s article. Sean Allen is a software engineer with deep expertise in building large distributed systems, stream processing, and confidential computing. He is a core contributor to the programming language Pony, which is designed for concurrency. Sean is a distinguished engineer at Antithesis. I was keen to talk with Sean due to his work on confidential computing at Microsoft, as well as his extensive work on the Pony language, and his passion for software correctness, which he works on fulltime at Antithesis. For this conversation, we set ourselves the challenge of discussing modern software engineering without using the phrase “AI” a single time. Read on to see if it’s possible in 2026… In this article, the questions are posed by me in bold font, with Sean’s words in normal font. Today we cover:
You can also watch this conversation on YouTube: 
An amusing detail: Sean and I discovered we share in common a first fulltime employer. We both worked at a company called ‘Sense/Net’ at the start of our careers, although they were totally separate businesses in different countries. The founders of each must’ve been fans of the foundational cyberpunk novel, ‘Neuromancer’ by William Gibson, where the ‘Sense/Net’ name comes from. Note: Antithesis is a podcast sponsor, but this deepdive is not sponsored by them. I’ve just been thinking a lot more about software correctness in the context of AI agents producing more code than ever, thereby creating opportunities for more bugs to ship to prod than ever. I wanted to learn more about this from an engineer with extensive experience in this area. 1. Software correctness & languages built for correctnessGergely: How do you define ‘software correctness’? Sean: “It’s down to whether my program does what I expect. I tend to talk about things in terms of ‘invariants,’ which is a more formal specification term. An invariant is a guarantee that my software does what’s expected of it. But here’s the problem: in lots of cases, people don’t know what they expect their software to do upfront! They know when it’s not working, but they don’t necessarily know what it means for it to be working.
Your personal definition of ‘beautiful code’ mirrors this.
Sean: “I was on the CoRecursive podcast when the subject of beautiful code in Ruby came up. I didn’t really know what people meant when they said ‘beautiful code’. Eventually, I came up with my own definition: beautiful code serves the purpose for which it was written and does not wake anyone up at 2 a.m.. That’s beautiful code to me!” Early in your career, you programmed in the Ada language. What did that teach? Sean: “When I was learning to program, I decided to pick a language and dedicate myself to it for a while. I ended up settling on Ada and C. Ada was driven in a lot of ways by what the US defense department wanted: a language which is very deeply specified and will not let you write incorrect programs. NASA and the US Defense Department were the types who this language was aimed at. Ada still exists today, and the pitch that Ada companies make is ‘so, you like Rust, how would you like more correctness guarantees?’ One of my great regrets is I could not get programs to compile in Ada because I didn’t know much about programming back then. It was so frustrating! Meanwhile, I could get C programs to compile, but they were segfaulting all the time! Over the years, I developed an intuition for how to do things in C so that my programs would not segfault and die. I had all these rules for writing concurrent C and C++ correctly. And even though I became really rigorous, I’m human and screwed up stuff. C gave me almost nothing in terms of correctness. It was just a big gun that I pointed at my own foot and shot it off with, over and over again. Looking back, I understand the reason my Ada programs wouldn’t compile was that they were fundamentally memory-unsafe. And so, Ada refused to compile, given the program would have ended up with memory corruption, a crash, or a data race.” What about languages in the ML family, like OCaml? Sean: “When it comes to programming languages, there’s a few families:
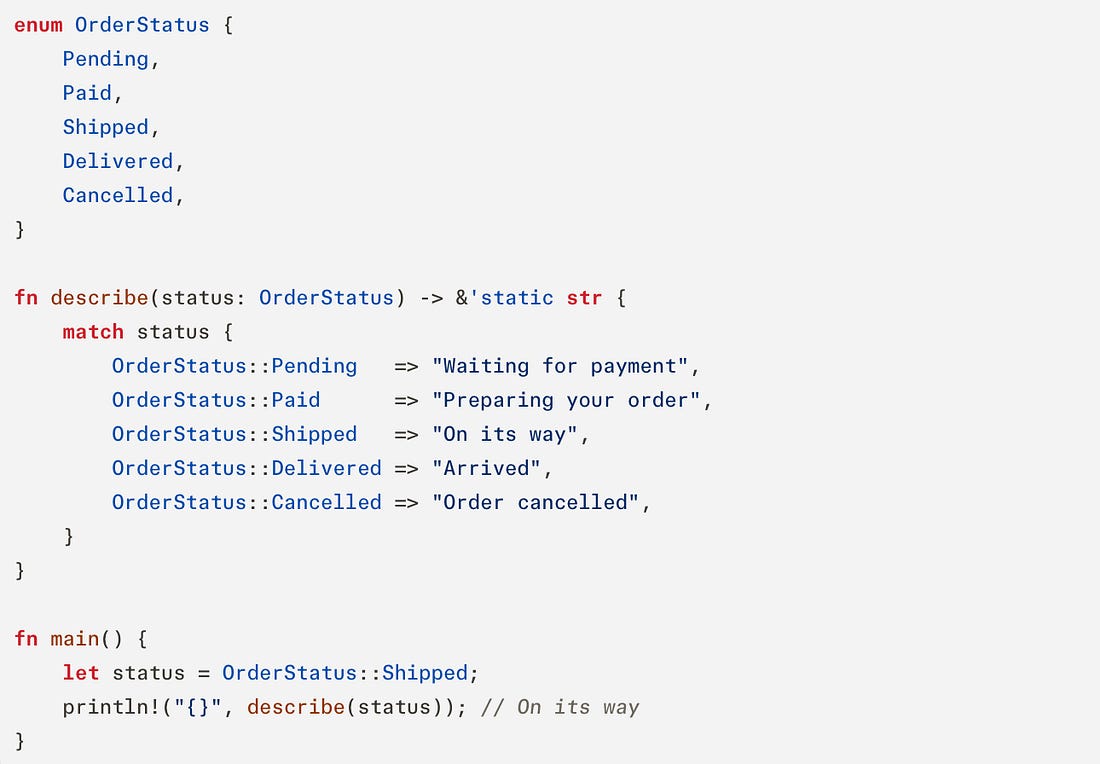
A sum type says ‘this value could be one of these things’, a bit like enumerations in Java. You combine that with pattern matching, and then with exhaustive matching. Say I have a sum type, which could be five different things. Instead of an if statement, I pattern match for which one it is. For example, here’s a sum type expressed in Rust:
Here’s the neat thing about a sum type: say you make a change to a sum type by going from five value types to six. As soon as you do it, the compiler will tell you every single place in your codebase where you’re not handling that sixth type, when combined with exhaustive matching! In other words, exhaustive matching turns every “forgot to handle the new case” bug into a compilation error. It is a gloriously wonderful experience to work with such a language.” 2. Does anybody care about testing?You’ve written “no one cares about testing. I don’t value tests,” but it’s odd to hear this from you as someone who does care about correctness. Sean: “I wrote that because people think of Antithesis as a testing company, and I don’t think of it that way. I think of it as a software verification and correctness company – which is very different. Tests are things that you do to verify that things are working, for things you have no better way to verify. The worst type of testing is manual testing. You can automate it, and get more and more sophisticated with automated tests, but you are still doing something at the late stage of development. You should do as much as possible before you get to testing. With ML languages, you can usually represent within the type system what the states are, and what the allowable transitions are. Once you have these in place, you can make sure that things can never transition to a state you don’t expect. Being able to do so is huge! In practice, when you’re trying to work out whether your system works, you’re not thinking about the entire thing all the way down. You’re only thinking about the stuff your type system will not allow you to express. This is the idea behind “make illegal states unrepresentable.” Playing devil’s advocate, you write the tests first in test-driven development (TDD), so that’s doing testing upfront, isn’t it? Sean: “I love TDD. I think it’s one of the best mechanisms for writing great APIs because you’re actively looking at how you’ll work with the thing. Also, the TDD community loves katas (little programming exercises). One of these is done in pairs: one person writes the test, and another writes the implementation which makes the test pass. The person writing the implementation is supposed to do the simplest possible thing. When people did these katas with me, they quickly discovered that I took writing the least amount possible to pass very literally. I would hard-code answers into the implementation to make their example-based tests pass. For example, if the only test is ‘what’s 2 + 2?’, I would just return a hardcoded ‘four’.
You get to property-based testing with TDD katas pretty quickly. The kata isn’t supposed to end until the person writing the tests is happy with the implementation, so the only way to ‘beat’ somebody who’s as literal as I was, is to start randomizing the inputs. The moment you randomize inputs, you’re in the land of property-based testing because you’re generating inputs to cover more space than you’d come up with in examples.” To be brutally honest, if I was writing the tests, I might think you were being a bit of a jerk! Sean: “Make that a bit more profane, and that is what people said to me on a regular basis! At one place where all the engineers did this exercise, whoever was paired with me would come out saying they were the only one who didn’t finish. But they’d also say, ‘I think I’m going to be much better at writing tests now.’ An awful lot of what was being tested with our katas were things you wouldn’t have to test with a stronger compiler. For years, I loved dynamic languages; Smalltalk is still one of my favorite languages, and I wrote a lot of Ruby, Perl, and Python. And I told myself I didn’t need the compiler’s help. Eventually, I realized I could get by without much compiler help because I mostly worked on small systems, and I could hold everything in my head. When I started working on bigger systems at bigger companies with more people, I started to value things like being able to delete a class and have the compiler tell me every single place that breaks.” 3. Workloads and correctnessYou’ve previously said that many people don’t have ‘workloads’ in their testing strategy. What are workloads? Sean: “Most people’s examples of property-based testing are simple:
However, if you want to apply property-based testing to a distributed system or database, then the workload is a combination of:
For example, let’s take a key-value store with three operations. The workload is the combination of:
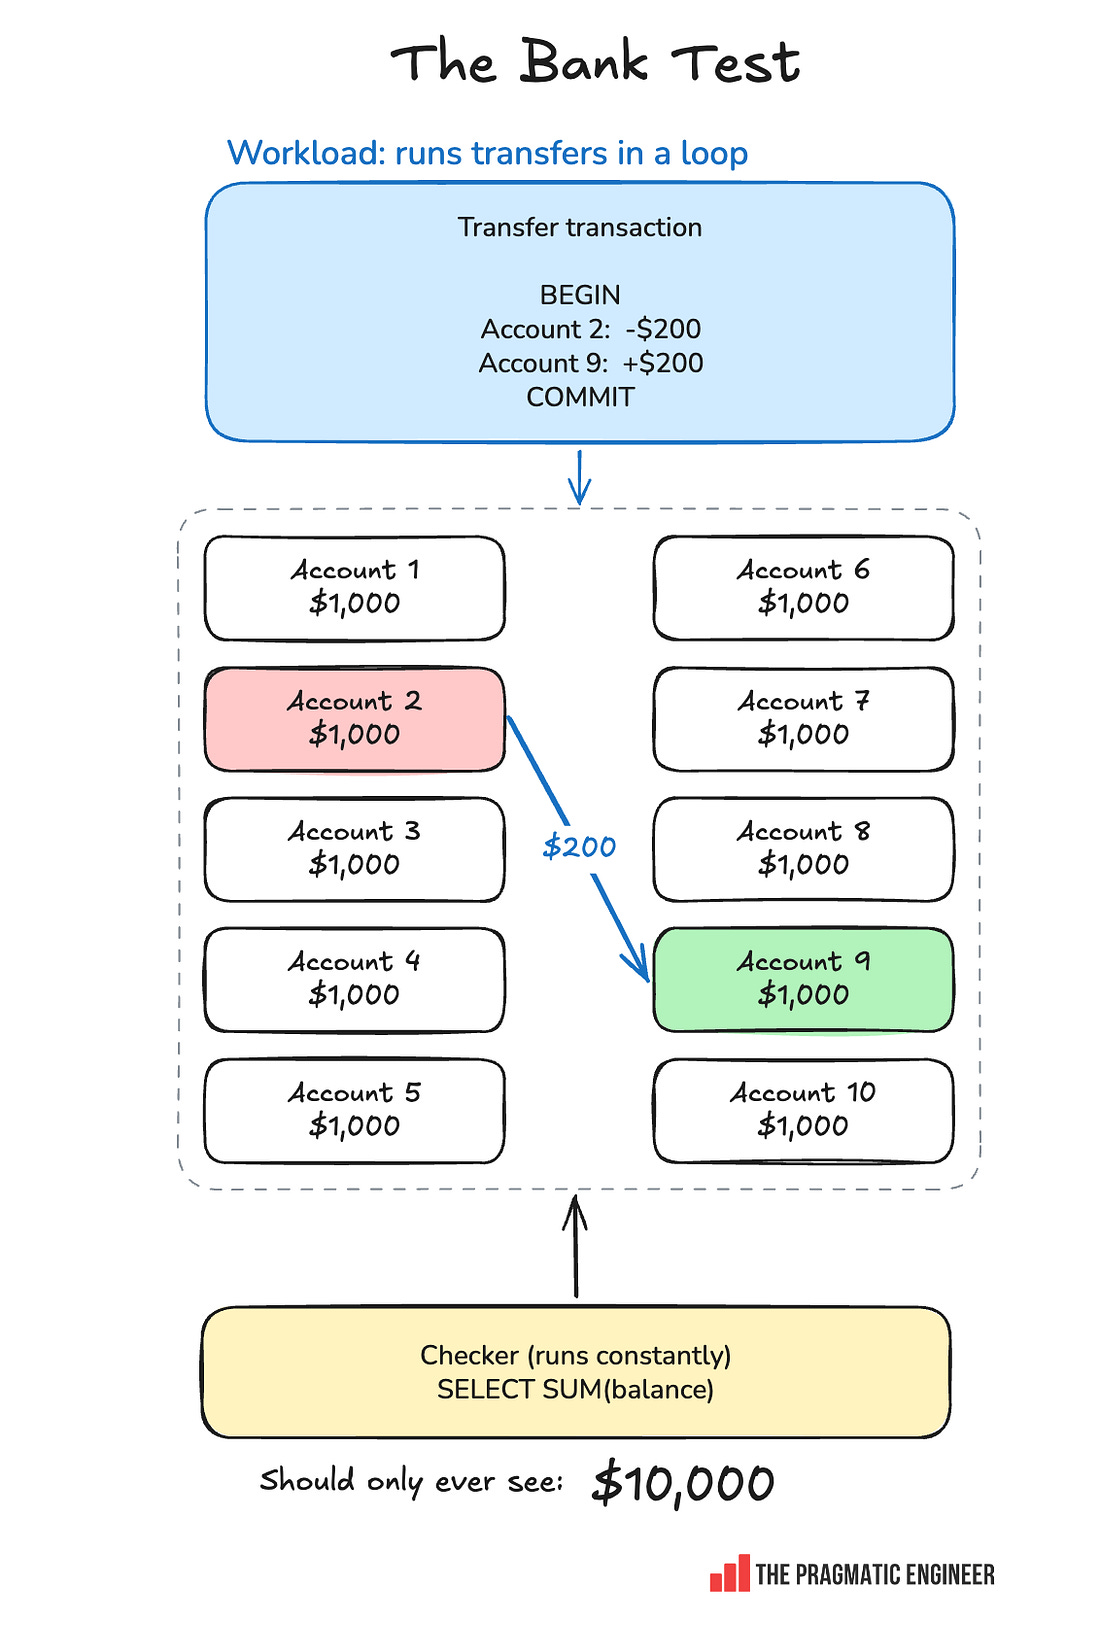
When reading about property-based testing, it’s easy to think that randomness is going to do the testing for you. For example, say you pick one of GET, PUT, and DELETE operations at random. By doing so, you won’t trigger many interesting places in your code because after a PUT, you’ll probably do a DELETE nearby. The odds of doing 10,000 PUTs in a row – pushing into areas where your store needs to swap to disk, garbage collect, or reshard – are tiny. Leaving all of this to chance is like walking when drunk: people don’t get very far from where they start.” What’s a specific workload that can help with testing? Sean: “There’s one workload commonly used for testing isolation guarantees in ACID databases, and it’s the single most important thing you want to guarantee in a database. It’s called the ‘Bank Test’: Let’s take this setup:
While running the workload which does transfers between accounts, you have another component constantly querying the total amount of money in the system. If the isolation guarantees hold, the only value it should ever see is 10,000.
If your database is good, you should never see weird failures. But if we’re talking about a distributed database and you run it in an environment where you introduce faults – like network ones between nodes or killing nodes – then all sorts of interesting bugs start popping out. Kyle Kingsbury made this famous with his Jepsen work on distributed systems safety research; it’s in the same vein as what we do at Antithesis. A simple workload exercises a core invariant: in this case, the invariant is ‘I should never see the effects of an operation that is happening inside of another transaction.’ So, with a workload, you set the rules and let things work themselves out? And with this Bank Test, we never specify how much money to transfer or when: it just describes how transfers happen? Sean: “Exactly. For software that’s been around for a while and has gone through rigorous testing, no bugs should pop out of something like the bank test. But bugs start popping out like crazy once you subject it to a Jepsen or Antithesis-type experience. That’s also the type of experience that happens all the time in production environments, which software engineer Lorin Hochstein does an incredible job of writing up in his incident breakdowns.” 4. Is quality not a “gate” or not?You believe quality is not a gate. The “gate” concept rests on a belief that quality is something you hold by keeping out the bad – but this isn’t how good teams stay good. What do you mean?
Sean: “This is a big reason why I prefer talking about correctness rather than testing... Subscribe to The Pragmatic Engineer to unlock the rest.Become a paying subscriber of The Pragmatic Engineer to get access to this post and other subscriber-only content. A subscription gets you:
|





Comments
Post a Comment